 Listicle
Best KPIs for Managed IT Services: Metrics That Matter
Last Updated: November 4, 2026
Quick Summary
The best KPIs for managed IT services fall into four groups: service desk performance, infrastructure reliability, technician productivity, and financial health. A balanced scorecard draws from all four, because a provider can hit ticket targets while quietly letting security and uptime slip.
- A reasonable target for routine tickets is a first response within one business hour, with urgent outages acknowledged in minutes.
- Technician use rate is billable hours divided by available hours, excluding paid time off, training, and internal meetings.
- An SLA clause should name the metric, target, measurement window, data source, and remedy for a miss.
- Report use monthly, segmented by tier and by client, and pair it with at least one quality metric.
- Track patch compliance, backup success rate, and multi-factor authentication coverage alongside performance metrics.
Table of Contents
- Why the Best KPIs for Managed IT Services Decide Whether Your Provider Is Actually Working
- The Best KPIs for Managed IT Services at a Glance
- Service Desk KPIs: Ticket Resolution, First Contact Resolution, and First Response Time
- IT Helpdesk Response Time Benchmarks: What Good Looks Like
- Uptime, Availability, and Reliability: The Infrastructure KPIs Clients Feel First
- Technician Use and Resource Use: The Productivity Side of the Scorecard
- IT Service Level Agreement Examples: Turning KPIs into Contractual Commitments
- How to Track Managed IT Service ROI: From Recurring Revenue to Client Outcomes
- Frequently Asked Questions
Why the Best KPIs for Managed IT Services Decide Whether Your Provider Is Actually Working
A managed service provider can promise 99.99% network uptime, but promises are not proof. According to Market.us managed services statistics, managed IT services benchmark at that uptime level and free up roughly 65% of internal IT staff time. Whether your provider actually delivers either result comes down to one thing: which metrics you track and how honestly they are reported.
Finding the best KPIs for managed IT services is the difference between a contract that looks good on paper and a partnership that measurably reduces downtime. A useful scorecard test is whether a metric tells a business owner something actionable, or just fills a report.
Below, we break down the metrics that matter, the formulas behind them, and the benchmarks that separate a proactive provider from a reactive one. But first, here is what most KPI guides get wrong: they list dozens of numbers and never say which ones to prioritize.
The Best KPIs for Managed IT Services at a Glance
The best KPIs for managed IT services fall into four groups: service desk performance, infrastructure reliability, technician productivity, and financial health. A balanced scorecard draws from all four, because a provider can hit ticket targets while quietly letting security and uptime slip.
Here is the quick comparison before we go deeper.
Quick Comparison Table: KPI, Formula, and What It Reveals
| KPI | Formula | What It Reveals |
|---|---|---|
| First response time | Time to first human reply ÷ tickets | Responsiveness |
| First contact resolution | Tickets closed on first touch ÷ total tickets | Helpdesk competence |
| Average resolution time | Total resolution hours ÷ tickets resolved | Service efficiency |
| Cost per ticket | Total support cost ÷ tickets handled | Operational efficiency |
| System uptime | Uptime minutes ÷ total minutes | Reliability |
| Technician use | Billable hours ÷ available hours | Productivity |
| Net-new recurring revenue | New MRR minus churned MRR | Growth health |
| SLA compliance | SLAs met ÷ SLAs committed | Contractual trust |
Service Desk KPIs: Ticket Resolution, First Contact Resolution, and First Response Time
Service desk metrics are the first place a client feels a provider's quality. Three numbers do most of the work: resolution time, first contact resolution, and first response time. Together they show whether the helpdesk is competent, fast, or simply busy.
Average Ticket Resolution Time and First Contact Resolution Rate
Average ticket resolution time is the total hours spent resolving tickets divided by the number of tickets resolved. A lower number signals efficiency, but only when paired with quality.
First contact resolution rate (FCR) is the percentage of tickets closed on the first interaction. High FCR means fewer repeat calls and less lost employee time. It is one of the strongest predictors of customer satisfaction in support operations.
First Response Time and Cost per Ticket
First response time measures how long a user waits before a human replies. Fast response matters more than fast resolution for most small teams, because the waiting itself stalls work.
Cost per ticket divides total support cost by tickets handled. It exposes whether automation and self-service are actually reducing effort, or just shifting it.
IT Helpdesk Response Time Benchmarks: What Good Looks Like
IT helpdesk response time benchmarks vary by ticket priority, and any provider quoting a single number is oversimplifying. A reasonable target for routine tickets is a first response within one business hour, with urgent outages acknowledged in minutes. Service Level Agreements (SLAs) typically guarantee 99.9% uptime or higher, according to Svitla's SLA guidance, and response commitments should be written with the same precision.
Ask a prospective provider three questions: What is your median first response time, not your average? What percentage of tickets hit FCR? And how do you report misses? A provider that publishes its own numbers, rather than hiding behind averages, is the one worth trusting.
Uptime, Availability, and Reliability: The Infrastructure KPIs Clients Feel First
Uptime is the metric clients notice instantly, because its failure is visible. Availability measures the percentage of scheduled time systems are operational; reliability measures how often they fail at all. Track both, plus mean time to recovery, which shows how fast the provider restores service after an incident.
Gartner's research on service metrics notes that modern service reporting is shifting from raw ticket volume toward infrastructure resilience and user experience. That shift matters: a provider can log few tickets while systems stay fragile. We recommend pairing uptime with recovery time so a resilient network is proven, not assumed. To put a dollar figure on outages, see how to calculate the cost of IT downtime.
Technician Use and Resource Use: The Productivity Side of the Scorecard
Use tells you whether the provider's team is deployed efficiently, but it is also the metric most often reported in a way that flatters the provider. Get the definition right before you trust the number.
Technician use rate is billable hours divided by available hours. Available hours should exclude paid time off, training, and internal meetings; if a provider includes those in the denominator, its use rate will look artificially low, and if it excludes them, the rate will look artificially high.
A common pattern is a target band rather than a single number. The right utilization band depends on the service mix, since a provider doing a lot of project work will run differently than one doing pure break-fix.
Report use monthly, segmented by tier and by client, and pair it with at least one quality metric.
Data sources matter here. Use typically comes from the PSA time-tracking module, reconciled against the RMM's device and alert counts so that monitored endpoints and contracted endpoints agree. If the PSA and RMM disagree on how many devices a client has, the resource use figure is not trustworthy.
IT Service Level Agreement Examples: Turning KPIs into Contractual Commitments
An SLA converts a KPI from a nice-to-have into an enforceable promise, but only if the clause names five things: the metric, the target, the measurement window, the data source, and the remedy for a miss. Most agreements name the first two and leave the rest vague, which is why disputes over SLA credits are so common.
Here is a workable pattern for a first response commitment:
"First response time is measured as the elapsed time between ticket creation and the first substantive human reply, excluding automated acknowledgments. Target: 60 minutes for priority-two tickets and 15 minutes for priority-one tickets, measured monthly. Reports are delivered by the fifth business day of the following month. If the monthly median exceeds the target in two consecutive months, the client receives a service credit equal to 5% of that month's recurring fee."
Note the choices embedded in that clause. It uses the median, not the average, so a single outlier does not distort the result. It excludes automated acknowledgments, which otherwise let a provider hit a 60-second response target without a human touching the ticket.
Apply the same five-part structure to the other core KPIs. For uptime, specify whether the measurement is calendar-month or business-hours, whether scheduled maintenance is excluded, and which monitoring system is the source of truth. For first contact resolution, define what counts as "first contact" and whether reopened tickets count against the rate.
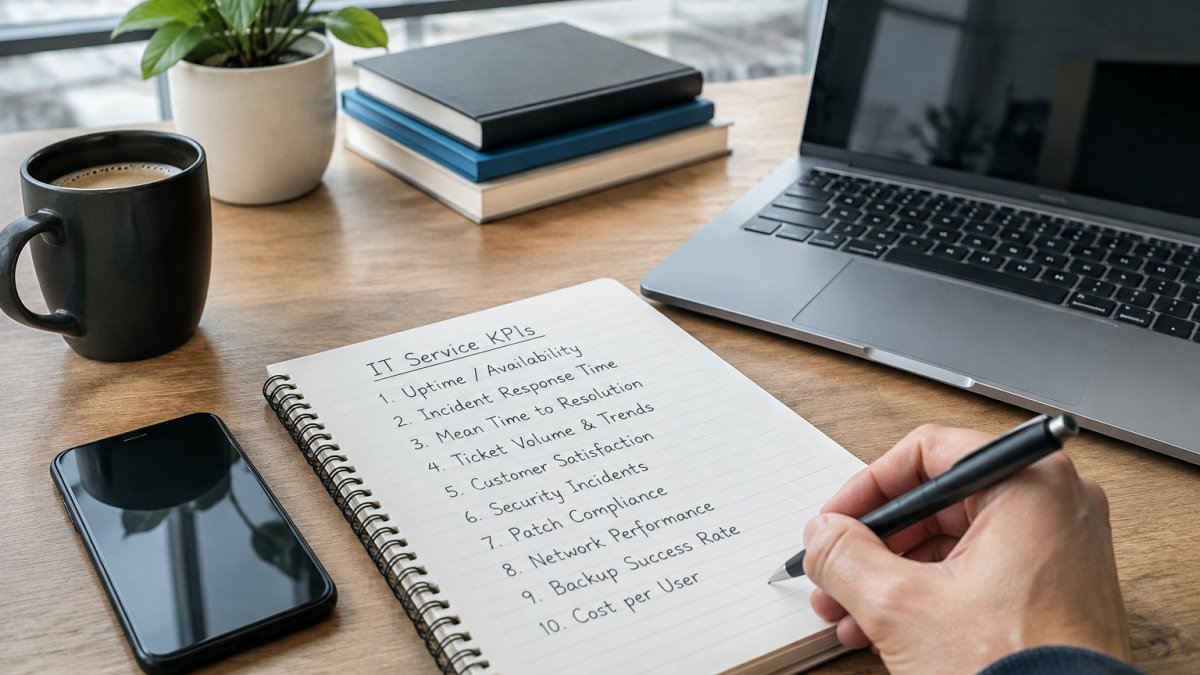
Security and compliance belong in the same document. A common pattern is to report patch compliance (endpoints patched within a defined window divided by total managed endpoints), backup success rate, and multi-factor authentication coverage alongside the performance metrics, with the same measurement window and reporting cadence.
Watch out: an SLA that promises 99.99% uptime without defining the measurement window, the excluded maintenance periods, and the monitoring source is effectively unenforceable. A provider can meet it on paper while missing it in practice. For concrete language to put in writing, see our guide on what to include in a managed services SLA.
How to Track Managed IT Service ROI: From Recurring Revenue to Client Outcomes
ROI tracking closes the loop between operational metrics and business value. On the provider side, track monthly recurring revenue, net-new recurring revenue, gross profit margin, and client retention. To compare those costs against the ROI your KPIs are meant to prove, see fully managed network, endpoint security, VoIP, and unlimited helpdesk. On the client side, track employee productivity gains, reduced downtime cost, and adoption of proactive services. Ready to act on the scorecard, you can see the fully managed service offering and sign up.
The TSIA's managed services research confirms that success is measured through a blend of customer satisfaction, revenue retention, operational efficiency, and profitability, not any single number. For a structured way to judge a provider against these metrics, read how to evaluate managed IT service providers.
Frequently Asked Questions
What are the most important KPIs for managed IT services?
The core set splits into three groups. Service desk KPIs include average ticket resolution time, first contact resolution rate, and first response time. Infrastructure KPIs cover system uptime, availability, and reliability. Business KPIs track monthly recurring revenue, gross profit margin, client retention, and churn. Managed IT services KPIs only work when all three groups are reviewed together, because fast tickets mean little if uptime is slipping or clients are leaving.
How do SLAs differ from KPIs in managed IT services?
An SLA is a contractual promise, while a KPI is the measurement you use to check whether that promise is being kept. For example, an IT service level agreement might promise a 15-minute first response time during business hours. The KPI is the reported figure showing your actual average response time each month. SLAs set the floor you must hit; KPIs give you the trend line so you can catch a slide before it becomes a breach.
What are good IT helpdesk response time benchmarks?
Benchmarks depend on priority and service hours. Response expectations should be set by ticket priority and service hours, and tracked against your own trend rather than an industry figure. Compare your own trend month over month rather than chasing a single industry figure, since client mix changes the baseline.
How can KPIs help improve managed IT service delivery?
KPIs turn vague complaints into specific problems. If first contact resolution drops from 75% to 60%, you know to look at technician training or knowledge base gaps rather than guessing. If ticket backlog grows while headcount stays flat, resource utilization is the number to examine. Modern service desks are moving away from raw ticket counts toward flow and user experience, so pair volume metrics with satisfaction and resolution quality to avoid rewarding the wrong behavior.
How do you track managed IT service ROI?
Start with the cost side: total monthly spend including helpdesk, endpoint security, network management, and VoIP. Then measure what that spend prevents or produces, such as downtime hours avoided, internal IT staff time freed up, and ticket volume handled without new hires. Managed IT services can free internal IT staff time, which you can translate into labor cost. Compare that combined value against your spend to get a defensible ROI figure.
If your current reports are full of ticket counts but short on outcomes, that is the signal to renegotiate or switch. VegaMSP builds every engagement around measurable uptime, endpoint security, and VoIP reliability, backed by unlimited helpdesk support and a Secure-IT-In-The-Box delivery model designed to eliminate downtime. Get started with VegaMSP and turn your IT scorecard into proof of performance.