 listicle
Is Proactive IT Maintenance Worth the Investment?
Table of Contents
- The Real Cost of Waiting: Reactive vs. Proactive IT Support
- What Proactive IT Maintenance Actually Includes
- A Preventive Maintenance Checklist for Business Networks
- Managed IT Services Pricing Guide: What Drives Your Monthly Cost
- Calculating ROI: Annual Savings and Downtime Avoided
- Where Proactive IT Maintenance Pays Off Most
- Conclusion: Weighing the Investment for Your Business
- Frequently Asked Questions
Last Updated: September 10, 2026
The Real Cost of Waiting: Reactive vs. Proactive IT Support
Most business owners underestimate what downtime costs until it happens. A Tuesday morning server failure stalls sales calls, halts order processing, and sends your team into firefighting mode for days. Whether proactive IT maintenance is worth the investment depends entirely on how you calculate cost. Many companies treat IT like a utility bill until something breaks, then scramble to cover emergency repair bills that dwarf a managed plan.
Proactive IT maintenance is the practice of monitoring, patching, and servicing systems on a scheduled basis to prevent failures before they occur, rather than repairing them after they break. The alternative, break-fix support, only responds once something has already failed.
How Break-Fix Costs Add Up Over Time
Reactive support looks cheaper because you only pay when something breaks. That math falls apart fast. A single emergency repair often includes after-hours labor rates, expedited hardware shipping, and lost productivity while systems are down. According to Uptime Institute's annual outage analysis, outages lasting more than an hour routinely cost organizations far more in lost business than the repair itself. Stack three or four incidents in a year and the total usually exceeds a predictable monthly managed plan.
What Proactive IT Maintenance Actually Includes
A managed maintenance program covers the recurring work that keeps infrastructure healthy: monitoring, patching, backups, and security updates. It replaces waiting for failure with scheduled intervention. But "proactive maintenance" hides a lot of operational detail, and the detail is where the investment either pays off or quietly wastes money.
Remote Monitoring and Patch Management
Remote monitoring and management (RMM) agents run on servers, workstations, and network gear and report telemetry to a central console. A useful RMM watches CPU, memory, disk queue depth, SMART disk health, service states, and event logs, then alerts when a metric crosses a threshold you set. The point is not to generate alerts; it is to generate the right alerts. An RMM tuned so loosely that technicians ignore the dashboard is the same as having no monitoring at all.
Patch management is the second pillar. Operating system and third-party application patches are staged, tested against a pilot group, then rolled out on a schedule. The Cybersecurity and Infrastructure Security Agency's guidance on vulnerability management notes that unpatched systems remain one of the most common entry points for breaches, and the reason is mechanical: attackers scan for known vulnerabilities at scale, so a missed patch window is an open door. Good programs separate critical security patches (fast track, often within days) from feature updates (slower track, tested first).
Backup, Verification, and Restore Testing
A backup that has never been restored is a hope, not a plan. Mature programs run three layers: local backups for fast recovery, offsite or cloud copies for disaster recovery, and immutable or air-gapped copies ransomware cannot encrypt. Verification separates a real program from a checkbox: schedule a quarterly restore drill to an isolated environment and log the result with a timestamp and the name of the person who ran it.
Endpoint Security and Identity Hygiene
Endpoint detection and response (EDR) tools watch for behavioral anomalies, not just known signatures. Identity hygiene matters just as much: disabling stale accounts, enforcing multi-factor authentication, and reviewing privileged access on a schedule. Many incidents trace back to a credential that should have been revoked months earlier.
Network and Hardware Lifecycle Management
Firewall rule reviews, firmware updates on switches and access points, UPS battery tests, and a documented hardware age inventory all belong here. The lifecycle piece is most often skipped: flagging devices within 12 months of end of life lets you budget replacements on your schedule instead of paying rush shipping when something dies on a Friday afternoon.
The Tooling Layer
Proactive maintenance runs on software: RMM platforms for monitoring and automation, PSA (professional services automation) tools for ticketing and time tracking, patch management modules, backup and disaster recovery platforms, and EDR consoles. The vendor matters less than integration: an RMM that does not feed the ticketing system creates blind spots, and a backup platform that does not alert on failed jobs creates false confidence.
The Transition Roadmap: Reactive to Proactive Without Disruption
Most articles explain why to switch and stop there. The harder question is how to move without breaking the business mid-transition:
- Discovery and documentation (weeks 1-2). Inventory every device, application, and vendor contract. You cannot monitor what you have not cataloged.
- Stabilize the worst risks first (weeks 2-4). Fix failed backups, missing patches on internet-facing systems, and expired antivirus licenses before anything else.
- Deploy monitoring in observe-only mode (weeks 3-6). Collect data without acting on it, so you learn the environment's normal baseline before you start changing things.
- Turn on automated remediation gradually (weeks 6-10). Start with low-risk actions like disk cleanup and patch staging, then expand.
- Shift the helpdesk model (ongoing). Route new tickets through the proactive workflow so recurring issues get root-caused instead of re-closed.
What Proactive Maintenance Is Not
It is not a guarantee of zero downtime. Hardware fails, vendors ship bad updates, and users click things they should not. The realistic promise is fewer unplanned incidents, shorter recovery times, and a predictable cost structure instead of surprise invoices.
A Preventive Maintenance Checklist for Business Networks
A preventive maintenance checklist for business networks turns vague good intentions into a repeatable monthly routine. Here's a practical starting point for any IT provider or internal admin:
- Verify all backups completed and test one restore per month
- Apply pending OS and application patches on a staged schedule
- Review antivirus and endpoint protection logs for missed threats
- Check disk space, memory, and CPU trends on servers and workstations
- Audit user accounts and remove access for departed staff
- Test uninterruptible power supplies and battery health
- Review firewall rules and confirm no unauthorized changes
- Document hardware age and flag devices nearing end of life
Managed IT Services Pricing Guide: What Drives Your Monthly Cost
Managed IT services pricing guide figures vary widely because cost is driven by scope, not a flat rate. Providers typically price on user count, device count, and how much of your stack they manage.
Per-User, Per-Device, and All-Inclusive Models
Three pricing structures dominate. Per-user pricing charges a set fee per employee, suiting stable headcounts. Per-device pricing counts servers, workstations, and network gear, fitting shared-equipment environments. All-inclusive models bundle network, endpoint, VoIP, and helpdesk support into one predictable figure. VegaMSP delivers a professional, authoritative "Secure-IT-In-The-Box" solution, providing fully managed network services, robust endpoint security, and seamless VoIP integration to eliminate downtime for businesses ready to scale with confidence. Our comprehensive approach, bolstered by unlimited helpdesk support, ensures your IT infrastructure is secure, reliable, and perfectly aligned with your growth objectives. We empower your team to focus on core business functions, knowing their operations are efficient and protected.
| Model | Best For | Predictability | Scales With |
|---|---|---|---|
| Per-user | Stable headcount | High | Employee count |
| Per-device | Shared equipment | Medium | Device count |
| All-inclusive | Growing businesses | High | Overall scope |
Calculating ROI: Annual Savings and Downtime Avoided
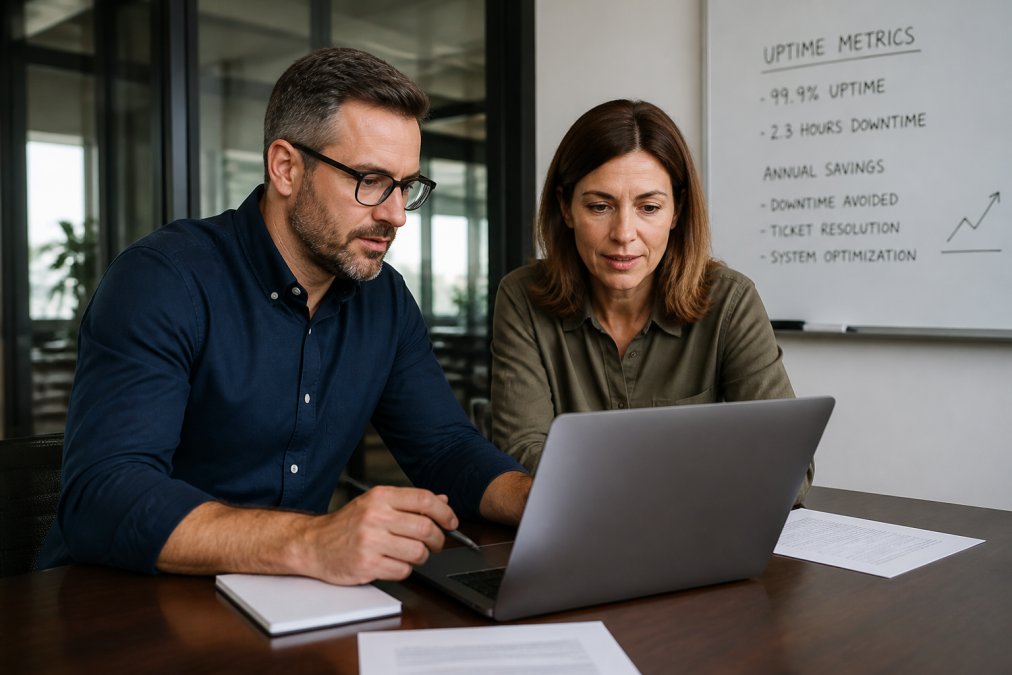
ROI comes down to comparing your current break-fix spend against a fixed managed rate, then adding the value of avoided downtime. Most businesses find the managed model pays for itself once they account for the true cost of an outage, but "true cost" is fuzzy, so the comparison never gets made. Here is a framework you can run in about 30 minutes with numbers you already have.
Step 1: Calculate Your Cost of Inaction
Start with your own historical data, not industry averages. Pull the last 12 months of IT incidents and answer four questions for each:
- How many hours was the affected system or team down?
- What was the fully loaded hourly cost of the people who could not work? (Salary plus benefits divided by 2,080 hours, multiplied by the number of affected staff.)
- What did the emergency repair cost? Include after-hours labor premiums, expedited shipping, and any contractor fees.
- What was the secondary cost? Lost sales, missed deadlines, customer credits, or compliance exposure.
Add those four numbers across every incident. That total is your annual cost of inaction, usually larger than owners expect, because nobody tracks the productivity line.
Step 2: Estimate Avoided Downtime
Not every incident disappears under a proactive model, but a meaningful reduction in frequency and duration is often observed. A reasonable planning assumption is to cut unplanned incident hours by a significant margin in year one, then improve as monitoring matures. Apply that reduction to your Step 1 total for estimated annual savings.
Step 3: Compare Against the Managed Fee
Take your estimated annual savings, subtract the annual managed services fee, and you have a rough first-year ROI. Even if the result is close to zero, the decision is usually favorable because the managed model converts unpredictable emergency spending into a flat, budgetable line item.
A Quick Self-Assessment: Where Does Your Business Land?
Score each statement from 1 (strongly disagree) to 5 (strongly agree):
- We know within minutes when a critical server or network device goes down.
- We test a backup restore at least once per quarter.
- Security patches are applied on a documented schedule, not when someone remembers.
- We have a current inventory of every device, application, and vendor contract.
- We can state our average cost per hour of downtime with confidence.
- We have a documented plan for replacing hardware before it fails.
- Access for departed employees is revoked within 24 hours (nist.gov).
- Our IT spending is predictable month to month.
Scoring: 32-40 means you are already operating proactively and the marginal gain from a managed plan is smaller. 20-31 means you have meaningful gaps a structured program would close. Below 20 means the reactive model is actively costing you money, and the ROI case is usually obvious once you run Step 1.
Industry Patterns Worth Knowing
The math shifts by industry because the cost of an hour of downtime shifts. A few recurring patterns:
- Professional services (legal, accounting, consulting): the dominant cost is billable hours lost, so the ROI case is straightforward and usually strong.
- Retail and e-commerce: revenue stops the moment the point-of-sale or storefront goes down, and the cost scales with transaction volume, so peak-season outages are disproportionately expensive.
- Healthcare and finance: regulatory exposure and reporting obligations add a cost layer that does not appear on the repair invoice, which tends to push the ROI case higher than pure productivity math suggests.
- Manufacturing and logistics: a single failed system can halt a production line or a shipment, so the per-hour cost is often the highest of any category.
The Predictability Premium
Predictable budgeting is the quieter benefit. Instead of surprise repair invoices, you get a known monthly figure that makes financial planning easier, often enough to justify the switch for growing companies, because leadership can invest in growth instead of holding cash for the next emergency.
Where Proactive IT Maintenance Pays Off Most
The return is highest where downtime directly stops revenue:
- Professional services firms lose billable hours the moment email or file access fails
- E-commerce operations lose sales with every minute the storefront is offline
- Healthcare and finance teams face compliance exposure when systems lapse
- Growing companies with 10-250 employees hit a ceiling where ad-hoc support can't keep pace
Smaller teams often assume managed services are for larger organizations. In practice, a 15-person firm with no dedicated IT staff gains the most, because every outage lands on the owner's desk.
The businesses that benefit most from proactive IT maintenance aren't the largest ones. They're the ones where a single outage costs more than a month of managed service.
Conclusion: Weighing the Investment for Your Business
Proactive IT maintenance is worth the investment for most businesses that depend on their systems to generate revenue. The reactive model only looks cheaper until you add up emergency labor, replacement hardware, and lost productivity. If your team has ever lost a full day to a preventable failure, the calculation already favors prevention.
VegaMSP delivers a professional, authoritative "Secure-IT-In-The-Box" solution, providing fully managed network services, robust endpoint security, and seamless VoIP integration to eliminate downtime for businesses ready to scale with confidence. Our comprehensive approach, bolstered by unlimited helpdesk support, ensures your IT infrastructure is secure, reliable, and perfectly aligned with your growth objectives. We empower your team to focus on core business functions, knowing their operations are efficient and protected. If you're ready to move from unpredictable repair bills to a stable, protected infrastructure, get started with VegaMSP and put your IT on a maintenance schedule that works.
Frequently Asked Questions
What is the difference between proactive and reactive IT support?
Reactive IT support, often called break-fix, waits for something to fail before technicians respond. You pay hourly for emergency repairs, and downtime hits without warning. Proactive IT maintenance uses remote monitoring, scheduled patch management, and preventive checks to catch issues before they cause outages. The cost comparison usually favors proactive support because you trade unpredictable emergency bills for a predictable monthly fee and fewer disruptions to your team.
How do you calculate the return on investment for managed IT services?
Start by adding up what downtime costs your business per hour, including lost productivity, missed sales, and overtime. Then estimate your current annual spend on emergency repairs, hardware replacements, and reactive help desk tickets. Compare that total to the flat monthly fee of a managed services plan. If your downtime and break-fix costs exceed the managed fee, the investment pays for itself. Ask providers for ROI-focused reporting to track savings over time.
Can proactive IT maintenance prevent data breaches and security incidents?
No system is breach-proof, but proactive maintenance reduces your exposure significantly. Regular patch management closes known vulnerabilities that attackers exploit. Continuous monitoring and threat detection catch suspicious activity before it spreads. Endpoint security tools block malware on individual devices. Businesses that skip these steps leave gaps that reactive support cannot close after an incident occurs. Proactive maintenance builds layers of defense that make a successful attack harder and costlier for criminals.
What specific tasks are included in a proactive IT maintenance plan?
A typical plan covers remote monitoring of servers, workstations, and network equipment. It includes automated patch management for operating systems and software, backup verification, and antivirus updates. Technicians perform routine hardware health checks, review event logs, and test disaster recovery procedures. Many providers also handle help desk tickets, vendor management, and strategic IT planning. The exact scope varies, so ask for a written checklist before signing a contract.
Is proactive IT maintenance worth it for a small business with 15 employees?
Small teams often benefit most because they lack in-house IT staff to catch problems early. One server outage or ransomware incident can halt operations for days and cost far more than a year of managed services. A managed plan gives you unlimited help desk support, endpoint security, and monitoring without hiring a full-time technician. The key is finding a provider whose pricing scales to your size, so you are not paying for enterprise-level infrastructure you do not use.
This article was reviewed by the VegaMSP editorial team.